
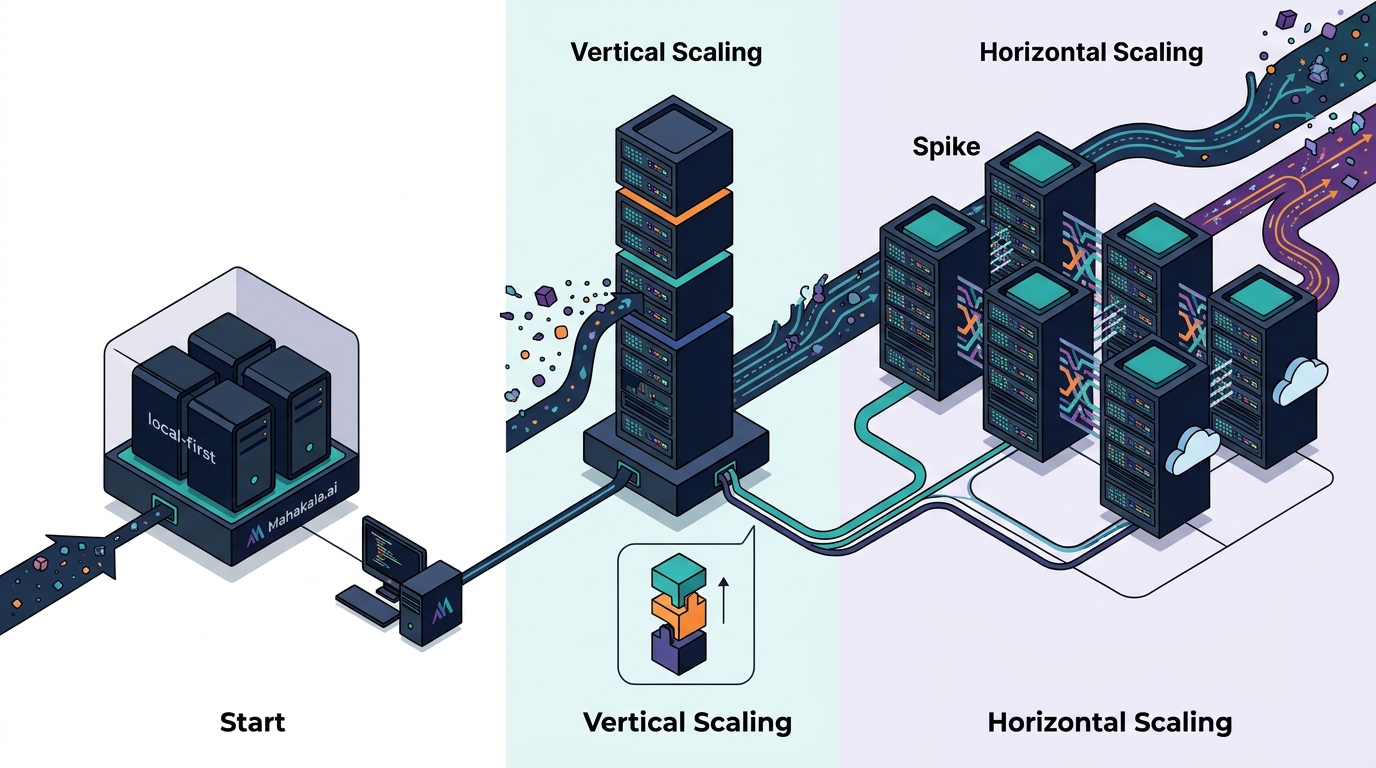
Choosing a hosting plan that grows with your startup requires balancing initial cost against long-term architectural flexibility. You need infrastructure that handles low traffic efficiently but scales vertically or horizontally as user demand spikes. Mahakala.ai approaches this by prioritizing local-first execution, which reduces dependency on expensive cloud tiers for routine tasks. This strategy allows teams to pay only for the compute resources they actively use, avoiding the bloat of over-provisioned shared or dedicated plans. For additional details, review the mahakalaai com.
Understanding the Cost of Static Infrastructure
Static hosting plans often lead to overpayment because they charge for maximum capacity regardless of actual usage. A startup might pay for a server capable of handling ten thousand concurrent users while only serving fifty. This inefficiency drains capital that could be better spent on product development. The core issue is the mismatch between fixed billing models and variable startup workloads. For additional details, review the Frequently Asked Questions.
Cloud providers typically address this with pay-as-you-go models, but complexity can still drive costs up. If your application requires constant high-performance inference or data processing, cloud bills can escalate rapidly. Mahakala.ai mitigates this by running open-weight models locally on consumer-grade hardware. This local-first processing acts as the primary source of truth for many tasks, reserving cloud resources only for complex escalations. By keeping routine operations on-device, you significantly reduce the volume of data sent to the cloud, directly lowering bandwidth and compute costs. For additional details, review the About.
The Role of Hybrid Escalation in Cost Control
Hybrid escalation routing is a critical mechanism for managing expenses in a scalable environment. This architecture automatically routes complex queries to cloud acceleration only when necessary. For simpler tasks, the system relies on local execution, which is effectively free after the initial hardware investment. This dynamic routing prevents the constant drain on cloud credits that occurs in purely cloud-based setups.
Consider a development team using autonomous agents for code generation. If the agent can resolve a syntax error locally using its native C++ inference kernel, no cloud API call is made. However, if the task requires extensive web research or large-scale data analysis, the system escalates to the cloud. This selective usage ensures that your billing is tied to actual complexity rather than raw request volume. It creates a natural cost ceiling for routine operations while maintaining the ability to scale for heavy loads.
Evaluating Hardware vs. Cloud Trade-offs
Optimizing for Long-Term Architectural Flexibility
Additionally, consider the impact of multi-agent orchestration on your infrastructure. Coordinating multiple autonomous agents can be computationally intensive. A scalable plan must handle this concurrency without degrading performance. By using a native desktop environment that optimizes resource allocation, you can run multiple agents locally. This reduces the need for expensive cloud orchestration services. The implication is that your infrastructure costs remain stable even as your team expands and adds more complex workflows.
Key Takeaways
- Static hosting plans often lead to overpayment due to fixed capacity charges that do not reflect actual usage.
- Local-first processing reduces cloud dependency by handling routine tasks on-device, lowering overall costs.
- Hybrid escalation routing ensures cloud resources are only used for complex tasks, optimizing spend.
- Data sovereignty achieved through local storage reduces the need for expensive secure cloud storage tiers.
- Phased scaling from local hardware to cloud nodes allows for controlled capital expenditure.
- Unified interfaces for managing local and cloud resources simplify monitoring and cost adjustment.
Frequently Asked Questions
What is local-first processing in the context of AI hosting?
Local-first processing is an architectural approach where AI models execute primarily on local hardware, using cloud resources only for specific escalations. This method reduces latency and cost by keeping data and computation on-device.
How does hybrid escalation affect monthly hosting costs?
Hybrid escalation affects monthly costs by limiting cloud usage to complex tasks only. Routine operations run locally, which significantly reduces the volume of billable cloud compute and bandwidth.
Can consumer-grade hardware handle scalable AI workloads?
What is the main advantage of data sovereignty in hosting?
The main advantage of data sovereignty is that sensitive data remains on local storage, reducing security risks and the need for expensive secure cloud storage. This also ensures compliance with strict data privacy regulations.
How do I know when to scale from local to cloud?
You should scale from local to cloud when local hardware consistently reaches capacity limits during peak demand. Monitoring resource usage through a unified interface helps identify these thresholds accurately.
Does local processing eliminate the need for cloud hosting entirely?
Local processing does not eliminate the need for cloud hosting entirely, but it significantly reduces the volume of cloud usage. Cloud resources are reserved for tasks that exceed local computational capabilities.
Conclusion
Selecting a hosting plan that grows with your startup requires a strategic approach to resource allocation. By leveraging local-first execution and hybrid escalation, you can minimize costs while maintaining scalability. Mahakala.ai provides the tools to manage this balance effectively, ensuring your infrastructure evolves with your business needs. To explore how this architecture fits your specific workflow, visit the Mahakala.ai homepage. Learn more: mahakalaai com.